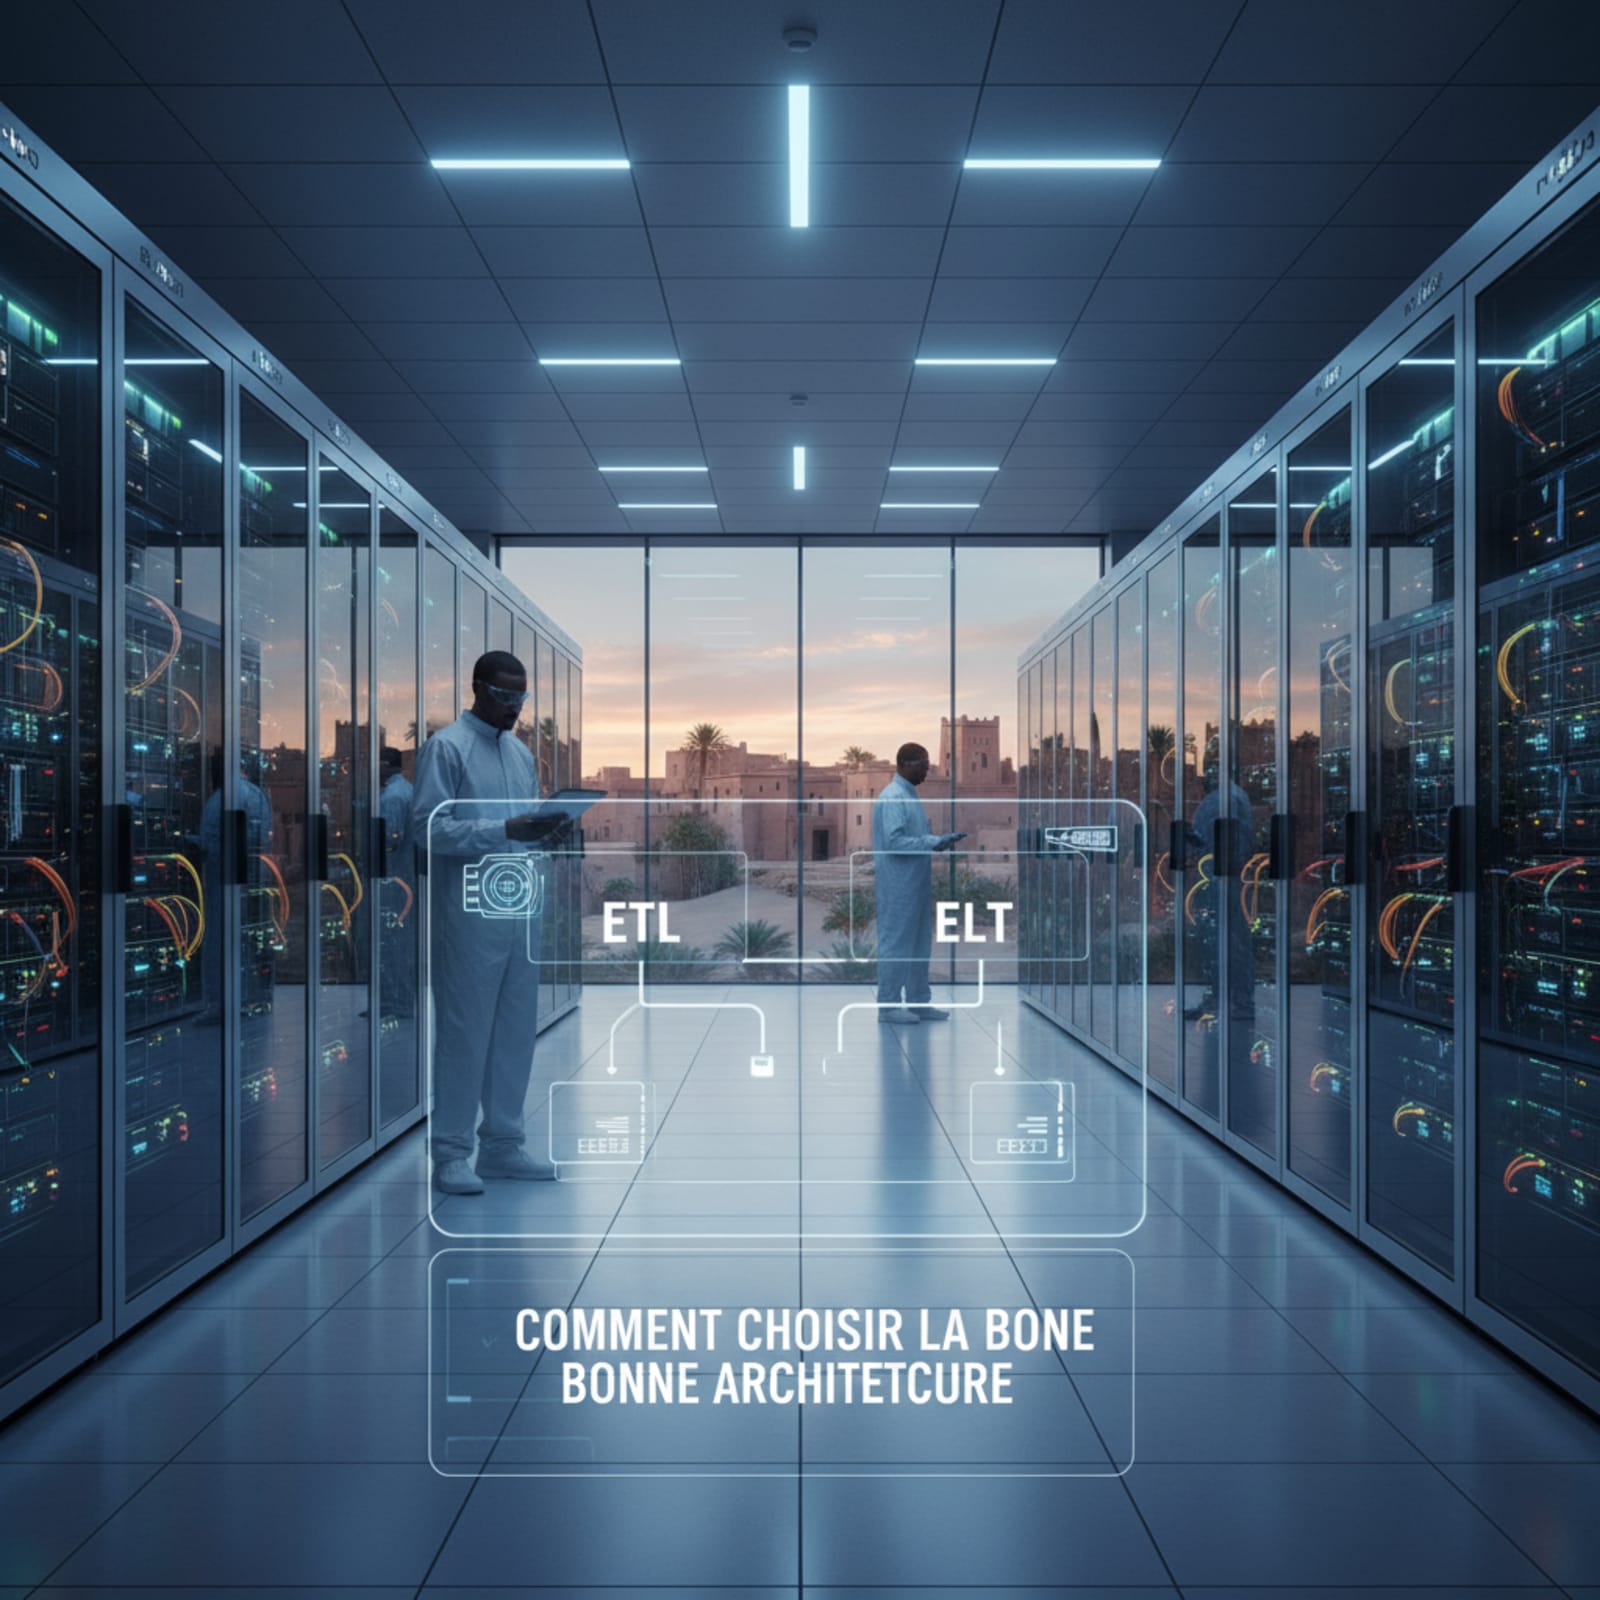
The major difference between ETL and ELT lies in when and where data transformation takes place. In ETL (Extract, Transform, Load), data is cleaned on an intermediate server before being loaded into the warehouse. In ELT (Extract, Load, Transform), raw data is loaded directly into the cloud data warehouse, which uses its own computing power to execute SQL transformations later.
When redesigning a business intelligence system or building a new data pipeline, Moroccan decision-makers face a major technical trade-off. Two IT service providers based in Casablanca might propose two diametrically opposed approaches to meet the same reporting needs. One swears by traditional ETL, while the other pushes for a modern, cloud-based ELT architecture. For an IT department or a finance department, this choice is far from trivial, as it directly impacts infrastructure costs, the speed of access to performance reports, and the autonomy of business teams. Understanding the fundamental difference between these two information processing philosophies is essential before validating a structuring technology investment.
Two Acronyms, Two Philosophies
To clarify the debate, it is helpful to break down the three key stages of data integration that make up these acronyms. The letter E stands for extraction, which means retrieving raw data from your various sources such as your ERP, CRM, accounting files, or production databases. The letter T represents transformation, which encompasses cleaning, formatting, deduplication, and applying business rules to make the data usable. Finally, the letter L corresponds to loading, which consists of storing this ready-to-use data in a final destination database dedicated to analysis.
The crucial difference between ETL vs ELT lies simply in the execution order of these steps and where the transformation takes place. In an ETL workflow, the transformation occurs in a dedicated intermediate server before the data reaches the final warehouse. Conversely, the ELT model first loads raw data directly into the destination warehouse and uses the latter's computing power to perform all necessary transformations. This shift in the transformation phase profoundly changes the dynamics of your data integration projects.
Classic ETL and Its Constraints
The historical ETL approach was born at a time when storage and computing power in destination databases were extremely expensive. To avoid overloading the BI server with heavy computing operations, a middle server, often called a staging server, was created to execute all transformation rules. This method ensures that only perfectly clean, structured, and aggregated data enters the final data warehouse. Major retail or industrial players in Morocco still use these highly secure pipelines to consolidate their monthly financial reports.
However, this traditional architecture has significant limitations when facing the explosion of data volumes. Creating a data pipeline in the form of a rigid ETL requires substantial initial development time. Every change to a business rule or the addition of a new column requires the intervention of a specialized engineer to modify the intermediate schema. Furthermore, the staging server represents a technical bottleneck. If daily data volumes suddenly double, processing can spill over into business hours and slow down access to BI dashboards.
ELT and the Shift to the Cloud
The democratization of cloud computing and the emergence of modern data warehouses like Snowflake, Google BigQuery, or Amazon Redshift have completely redefined the landscape. These modern technologies offer virtually unlimited computing power and storage that can scale instantly on demand. It is in this technological context that ELT has taken on its full meaning. Since the destination warehouse is now extremely powerful and capable of processing terabytes of data in seconds, why bother with an expensive and complex-to-maintain intermediate server?
With ELT, data is extracted from all company sources and immediately loaded, in its raw or semi-structured form, into the centralized data warehouse. Transformations are then performed directly within this warehouse using SQL. This approach makes it possible to preserve the complete history of raw data. If your analysts decide in six months to change the method for calculating sales margins, they do not need to rebuild the entire data pipeline from the source. They simply need to re-run a new SQL query on the raw data already stored in the cloud.
What the Choice Changes for Teams
Beyond the purely technical aspect, the trade-off between ETL and ELT transforms the daily routine of your employees. In a classic ETL setup, business analysts depend entirely on the IT team or external service providers for even the slightest report updates. If the marketing department of a major retailer like Marjane Holding or Label'Vie wants to cross-reference loyalty data with a new digital advertising campaign, they must submit a technical request that can take several weeks to materialize.
ELT fosters a much more agile and decentralized data culture. Data engineers focus solely on the plumbing, ensuring that raw data arrives reliably and securely in the warehouse. Once the data is available, business analysts and financial controllers can take over. Using modern, collaborative SQL-based transformation tools, they create their own clean data tables and key performance indicators, significantly reducing the time to deliver strategic insights.
Deciding Based on Volume and Skills
The final choice should not be dictated by a simple technology trend, but by a pragmatic analysis of your business context. Traditional ETL remains an excellent option if you handle stable, highly confidential data volumes and already possess high-performance on-premise infrastructure. It is also preferred when strict compliance rules require masking or anonymizing sensitive data before it even leaves local production servers.
On the other hand, if your company is committed to a cloud transition, manages growing and changing data volumes, and seeks to give more autonomy to its analytical teams, ELT is the natural choice. To succeed in this complex technological transition and design a high-performance, scalable data architecture, guidance from data engineering experts is essential. The consultants at Data Scale Business help you design, secure, and deploy modern data pipelines perfectly tailored to the economic and operational realities of your organization.